A new website is invisible until a crawler finds it, reads it, and a search engine or an AI answer tool decides to keep it. This guide is the practical path: what to do on day 0, in the first week, and on an ongoing basis, so Google, Bing, ChatGPT search, Perplexity, Claude, Gemini, Copilot and the training crawlers can see the pages you actually want them to see.
It will not make a page appear in results on a timer. Indexing is a request, not a booking. What you can do is remove the delays you control, tell the right systems that the pages exist, and leave the doors open for the crawlers you want.
What these words mean
A crawler (also called a bot or a spider) is a program that fetches pages the way a browser does, then hands the content to a search engine or an AI system. A user agent is the name it uses to introduce itself, in the HTTP request and often in your server logs.
An index is the catalogue a search engine or an answer tool uses when it replies to a question. Getting indexed means a page has been crawled and stored in that catalogue. It does not, on its own, mean the page will rank well or be cited in an AI answer.
robots.txt is a small text file at the root of your site (for example, https://www.example.com/robots.txt). It tells well-behaved crawlers which paths they may request. It is a request, not a lock on the door. Some user-triggered fetchers, and some poorly behaved scrapers, ignore it.
A sitemap is a list of the public URLs you want discovered, usually in XML. You submit it to search engines and you can also point to it from robots.txt. A sitemap is a hint, not a promise that every URL will be crawled or kept.
A canonical tag is a short line in a page’s HTML that names the preferred URL for that content, so engines don’t treat https and http, or www and non-www, as unrelated pages.
Training data is the text and other material used to teach a generative model. Search and answer crawlers are not the same as training crawlers, and a control that covers one often leaves the other alone.
Why a new site takes time
A brand-new host has no crawl history, few links from other sites, and no record of being useful. Search engines find URLs from links, sitemaps and pings, then decide whether to crawl, and later whether to keep the page in the index. Google’s own documentation says crawling after a recrawl request can take a few days to a few weeks, and that indexing is not guaranteed even when a page meets the technical rules.
“As soon as possible” here means you have removed the delays you control: a robots.txt that blocks the public pages, a missing sitemap, content that exists only after JavaScript runs, a CDN that is silently stopping AI crawlers, or a publish process that never pings the engines that accept IndexNow. It does not mean you can skip the engine’s own quality checks and scheduling.
The path, in three stages
The work falls into three stages: open the doors on day 0, ask for a crawl in the first week, and keep the map current after that.
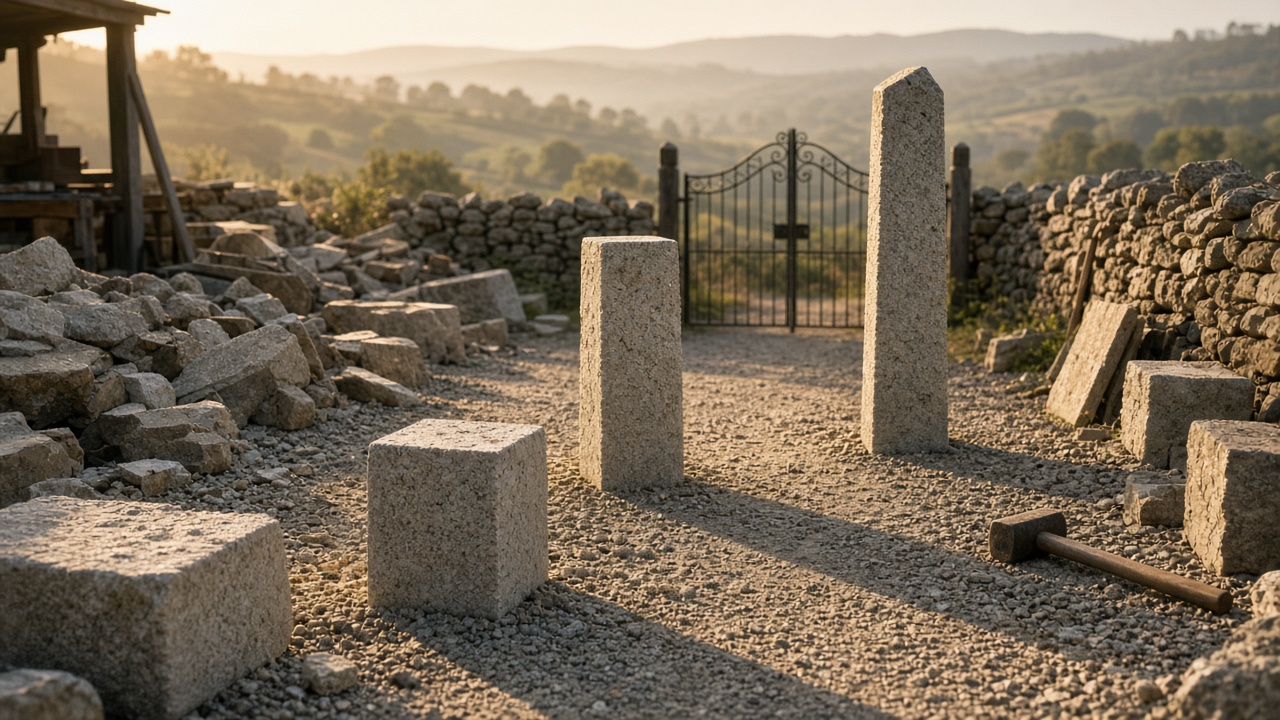
| Marker | What it marks |
|---|---|
| The low granite cube on the path | Day 0, when you open the site, add robots.txt and a sitemap, and verify Search Console and Bing |
| The chest-high pillar further along the path | The first week, when you request indexing for key pages, turn on IndexNow, and check the CDN isn’t blocking crawlers |
| The tall waystone beside the gate | The ongoing work of keeping the sitemap current, earning citations, and deciding which training crawlers to allow |
Day 0: open the doors
- Put the site on the public internet with HTTPS. The pages you want found must load for a visitor who is not logged in. A staging header, a password gate or a “coming soon” splash will stop most crawlers in their tracks.
- Write real pages and link them with ordinary HTML links, the kind that look like
<a href>in the page source, from the home page and the main sections. A page that is only reachable through a search box or a scripted click with no real URL is easy to miss. - Put the words you want indexed in the first HTML response from the server. Google can render JavaScript with Chromium, and it still says server-side rendering or pre-rendering is a great idea, because it makes the site faster for people and for crawlers, and not all bots run JavaScript.
- Add a
robots.txtfile at the site root. Allow the public pages. Block only the paths you truly want hidden, such as admin screens, carts or internal search-result URLs. Include aSitemapline that points at your XML sitemap. On this news site the file is the short WordPress default: it blocks/wp-admin/, allows the admin-ajax endpoint, and points at the sitemap. It does not single out AI crawlers. On another site I run, kislap, the file allows public pages and blocks CCBot and Bytespider, plus some search and API paths. - Publish an XML sitemap of the public URLs. Google’s limit is 50,000 URLs or 50 MB uncompressed per sitemap file; use a sitemap index if you need more than one file. If you include a lastmod date, keep it accurate.
- Verify the site in Google Search Console. That means proving you control it, so you can submit sitemaps, inspect URLs and see indexing reports. Google accepts an HTML file at a set URL, a meta tag on the home page, a DNS record (the method you need for a Domain property, which covers every protocol and subdomain), or an existing Google Analytics or Google Tag Manager tag you can edit. Many hosts and WordPress plugins can do this for you. Leave the verification token in place, or you will lose access. The full verification help page walks through each method.
- Submit the sitemap in the Search Console Sitemaps report. You can also submit through the Search Console API, or rely on the Sitemap line in
robots.txt. Treat the sitemap as a discovery aid, not a crawl guarantee. - Add the site in Bing Webmaster Tools. If the property is already verified in Search Console, the fastest path is to import it. Bing asks for permission, shows your verified sites and their sitemaps, and verifies the ones you select automatically. You can also add a site by hand and verify it with a file, a meta tag or a DNS record. Bing says it usually takes 48 hours for analytics to appear. Microsoft Copilot is powered by Bing’s index, so this step also serves Copilot.
- Turn on IndexNow for the search engines that have adopted it, so they get a ping when you publish, update or delete a public URL. I already run that hook on this news site. The separate IndexNow guide covers the protocol, the key file, the endpoints and the current participants. Google is not one of them, which is why the Search Console sitemap path still matters.
- If the site sits behind Cloudflare or another content delivery network, a CDN, open the bot and AI-crawler controls and confirm that search and answer crawlers are not blocked. On Cloudflare this lives under Security settings as AI Crawler and Agent access policies, and some accounts still have an older Block AI bots style switch. A block at the edge stops a crawler even when
robots.txtallows it. Cloudflare’s current documentation says new domains default to Allow for Search, Agents and Training, but a later change, a host template or Bot Fight Mode can still get in the way. Bot Fight Mode can challenge a bot even when a firewall rule would allow it. - Add a canonical tag on each public page, pointing at the preferred URL: HTTPS, the host you want, and no tracking parameters.
- Search the live HTML for an accidental noindex tag, and load the site in a private window to confirm it is the real public version.
First week: ask for a crawl and stay findable
- In Search Console, open URL Inspection for the home page and a handful of your most important URLs, then use Request indexing. There is a daily limit per property; Google does not publish the exact number for that button. Requesting the same URL again and again does not speed it up. For a large set of URLs, use the sitemap. A request does not guarantee the page will be indexed, and Google says the recrawl can take a few days to a few weeks.
- Do not send ordinary pages to Google’s Indexing API. That API is limited to JobPosting pages and livestream BroadcastEvent pages.
- Confirm the sitemap shows as successful in Search Console and in Bing Webmaster Tools, and fix any rejected URLs.
- Walk the site as a new visitor. Every important page should be a few ordinary links from the home page.
- If you add structured data, which is machine-readable markup that describes the page, keep it consistent with the visible text. Google says you do not need a special AI-only file or a special schema.org type to appear in AI Overviews or AI Mode.
- Tell people about the site in places that already make sense: a company listing, a professional profile, a genuine mention on a site you already belong to. Links and citations help engines discover you. Do not buy or invent them.
- Watch the Page indexing report and the robots.txt report in Search Console, and fix anything that is blocking the public pages.
We’re excited to announce the new Search Console robots.txt report, available from the settings page. We’re also making relevant info available from the Page indexing report. As part of this update, we’re sunsetting the robots.txt tester. Check the updated help center page
November 15, 2023
Ongoing: keep the map current
- Keep the sitemap current as you add and remove pages.
- Keep IndexNow in the publish and update path, as described in the IndexNow guide.
- When you change
robots.txt, give crawlers time to notice. Several operators, including OpenAI, Perplexity and Meta, say a change can take around 24 hours because they cache the file. Google’s recrawl of the pages themselves can still take longer. - Earn mentions on trusted sites. Pages that other reliable sources cite are easier for both search engines and answer engines to treat as worth showing.
- Decide, deliberately, whether training crawlers are allowed. Review GPTBot, ClaudeBot, Google-Extended, Applebot-Extended, CCBot and Meta-ExternalAgent, which are covered below. Allowing them is a choice, not a booking. Inclusion in a later model, and the timing of any later use, are not something you can schedule or guarantee.
- An
llms.txtfile is optional. It does not replacerobots.txtor a sitemap. - Re-check CDN bot settings after a plan change or a platform migration.
- If you want to stay out of Google’s AI Overviews, AI Mode and related generative features in Discover, use Search Console’s Search generative AI control, which Google rolled out to all websites worldwide in August 2026. That control is separate from Google-Extended.
How AI search tools find pages
ChatGPT search, Perplexity, Claude’s search features, Google’s AI Overviews and AI Mode, and Microsoft Copilot do not all use the same crawler, and a training block does not automatically hide you from answers.
Google’s AI Overviews and AI Mode use the Google Search index. To be eligible as a supporting link, a page must be indexed and eligible to appear in Google Search with a snippet. Google’s documentation says there are no extra technical requirements, no special AI text file, and no special schema.org type. The same SEO basics apply: allow crawling in robots.txt and at the CDN, make pages findable through internal links, and keep the important content in text. Google-Extended does not control whether you appear in those Search features, and it is not a ranking signal. The Search generative AI control in Search Console, and the older preview controls such as nosnippet, are the Search-side switches. Barry Schwartz reported Google’s confirmation that Google-Extended does not apply to what was then called SGE, now AI Overviews.
Google SGE AI-generated answer showing content cards from sites that Google-Extended disallow, Google-Extended does not apply to SGE, Google told me
October 10, 2023
ChatGPT search uses OAI-SearchBot. If you disallow that bot, OpenAI says the site should not be used as a source in search answers, though it can still appear as a navigational link. GPTBot is a different bot, used for training generative foundation models. ChatGPT-User is a user-initiated fetch from ChatGPT, custom GPTs or GPT Actions; it is not an automatic crawl, OpenAI says robots.txt rules may not apply to it, and it is not used to decide Search appearance. The settings are independent. If both OAI-SearchBot and GPTBot are allowed, OpenAI may reuse a single crawl.
Perplexity uses PerplexityBot to build search results, and says that bot is not used to train foundation models. Perplexity-User is a user-initiated fetch and generally ignores robots.txt. Changes can take up to 24 hours.
Claude’s search indexing uses Claude-SearchBot. ClaudeBot is the training crawler. Claude-User fetches pages at a person’s request; Anthropic says this one respects robots.txt, which is a stricter stance than OpenAI and Perplexity document for their user fetchers.
Microsoft Copilot is powered by Bing’s index, so Bingbot and Bing Webmaster Tools are the search path.
Apple uses Applebot for search in Spotlight, Siri and Safari. If your robots.txt mentions Googlebot but not Applebot, Applebot follows the Googlebot rules. Applebot-Extended is a control token only; it does not crawl, and disallowing it opts you out of training Apple’s general-purpose foundation models without removing pages from Apple search. A nosnippet rule opts you out of use as extra context in Apple’s AI-generated answers.
A typical robots.txt already allows these crawlers if you have a User-agent: * group that only blocks admin or private paths. You add named groups when you want to allow one crawler and block another, or when a blanket AI block is already in the file and you need to open a specific door. Control tokens such as Google-Extended and Applebot-Extended are opted in by default unless you disallow them.
# Named allow rules, if you need to be explicit
# or to reopen a door after a blanket block.

User-agent: Googlebot
Allow: /

User-agent: Bingbot
Allow: /

User-agent: OAI-SearchBot
Allow: /

User-agent: PerplexityBot
Allow: /

User-agent: Claude-SearchBot
Allow: /

User-agent: Applebot
Allow: /

# Training crawlers and control tokens.
# Disallow these if you want to opt out.

User-agent: GPTBot
Allow: /

User-agent: ClaudeBot
Allow: /

User-agent: Google-Extended
Allow: /

User-agent: Applebot-Extended
Allow: /

User-agent: CCBot
Allow: /

User-agent: meta-externalagent
Allow: /

Sitemap: https://www.example.com/sitemap.xml
Check the CDN as well as the robots file. Cloudflare can allow or block verified crawlers by behaviour (Search, Agent or Training), and it can enforce a robots.txt Disallow at the edge if Bot Preference Sync is on. robots.txt alone does not technically prevent access.
We hear clearly that customers don’t want AI bots visiting their websites, and especially those that do so dishonestly. But you can block all AI bots. This feature is available for all customers:
December 15, 2024
llms.txt is a community proposal, started by Jeremy Howard and Answer.AI, for a curated Markdown overview of a site, usually published at /llms.txt. Version 1 appeared in September 2024 and version 2 in August 2026. It is not an IETF or W3C standard. Thousands of sites publish one, some documentation platforms generate it, and OpenAI, Anthropic and Google publish it for their own developer docs. That is not the same as a commitment by those products to read a third-party site’s llms.txt as a discovery or ranking signal. Google’s AI features documentation says you do not need a new machine-readable file to appear in AI Overviews or AI Mode. Treat llms.txt as an optional help file for agents, not as a substitute for a sitemap or for getting indexed in Search.
Google just put out its first official article on optimizing for AI search (AEO/GEO)!
May 15, 2026
TL;DR:
⭐️ SEO is still the foundation for AI search.
⭐️ Create non-commodity, “people-first” content.
⭐️ Ignore most “GEO/AEO hacks like chunking and llms.txt.
Crawler, operator and purpose
The table below is drawn from official documentation. Where a row is a control token rather than a separate crawler, that is stated in the purpose column.
| Crawler | Operator | Purpose | robots token |
|---|---|---|---|
| Googlebot | Search and answer (Google Search, including AI Overviews and AI Mode) | Googlebot | |
| Google-Extended | Training and grounding control token only; no separate crawler. Controls Gemini Apps and Vertex AI training and grounding. Does not affect Google Search inclusion, ranking, or AI Overviews | Google-Extended | |
| Bingbot | Microsoft | Search and answer (Bing Search, and Copilot, which uses Bing’s index) | bingbot |
| OAI-SearchBot | OpenAI | Search and answer (ChatGPT search) | OAI-SearchBot |
| GPTBot | OpenAI | Training of generative foundation models | GPTBot |
| ChatGPT-User | OpenAI | User-triggered fetch (ChatGPT, custom GPTs, GPT Actions). Not an automatic crawl; robots.txt may not apply; not used for Search appearance | ChatGPT-User |
| PerplexityBot | Perplexity | Search and answer; not used for foundation-model training | PerplexityBot |
| Perplexity-User | Perplexity | User-triggered fetch; generally ignores robots.txt | Perplexity-User |
| Claude-SearchBot | Anthropic | Search and answer (search indexing and result quality) | Claude-SearchBot |
| ClaudeBot | Anthropic | Training | ClaudeBot |
| Claude-User | Anthropic | User-triggered fetch; Anthropic says it respects robots.txt | Claude-User |
| Applebot | Apple | Search (Spotlight, Siri, Safari) | Applebot |
| Applebot-Extended | Apple | Training control token only; does not crawl. Disallowing it does not remove pages from Apple search | Applebot-Extended |
| CCBot | Common Crawl | Open web crawl, widely reused including for research and training | CCBot |
| Meta-ExternalAgent | Meta | Training foundation models, or product indexing | meta-externalagent |
| Meta-ExternalFetcher | Meta | User-triggered fetch; may bypass robots.txt | meta-externalfetcher |
Getting into training data
If you want your public pages in the pool that future models can learn from, the practical step is to allow the training crawlers and control tokens those operators document, and to leave the pages themselves publicly readable.
GPTBot is OpenAI’s training crawler. A Disallow tells OpenAI the content should not be used for training. ClaudeBot is Anthropic’s training crawler; Anthropic says blocking it signals that future materials should be excluded from training datasets. As of late October 2026 Anthropic also began recognising a more general machine-readable no-training signal, with ClaudeBot-specific robots rules taking priority over that general signal.
Google-Extended is a robots.txt product token with no separate HTTP user agent. Crawling still happens with Google’s existing user agents. The token controls whether crawled content may be used to train future Gemini models for Gemini Apps and the Vertex AI API for Gemini, and for grounding in Gemini Apps and Grounding with Google Search on Vertex AI. It does not change inclusion or ranking in Google Search, and it does not control AI Overviews or AI Mode. Google has said it intends to support a shared training-preference token in early 2027; that is a planned control, not a live universal switch.
Applebot-Extended, as noted above, is the opt-out token for training Apple’s general-purpose foundation models.
CCBot is Common Crawl’s crawler. Common Crawl is a non-profit that periodically crawls the public web and publishes the results in an open repository. Researchers and companies reuse that corpus, including for training. To opt out, Common Crawl documents a CCBot group with Disallow: /. You can verify a claimed CCBot hit through reverse DNS under crawl.commoncrawl.org. Allowing CCBot means a snapshot of a public page may appear in a later open crawl, which other people can then use. Blocking CCBot does not stop every other training crawler.
Meta-ExternalAgent crawls for uses such as training foundation models or improving products by indexing content. The robots token is meta-externalagent. Meta-ExternalFetcher is a user-requested fetcher and, Meta says, may bypass robots.txt. Changes can take up to 24 hours.
A copyright statement or a licence page on the site does not, on its own, replace these robots tokens. The operators above document robots.txt as the machine-readable control they will honour for the named crawler or token. Inclusion is still not a right you can enforce on a timetable: a crawler can skip you, a later training run can use a different snapshot, and a model release has no public queue you can join.
Checklist
Day 0: HTTPS and public pages, ordinary internal links, important text in the first HTML response, a robots.txt that allows public paths and names the sitemap, an XML sitemap, Search Console verification and sitemap submission, Bing Webmaster Tools (import from Search Console if you can), IndexNow for participating engines, CDN bot settings checked, canonical tags, no accidental noindex.
First week: Request indexing for the home page and key URLs, without repeating the same URL, and without using the Indexing API for ordinary pages. Confirm both sitemaps. Walk the internal links. Add structured data only when it matches the visible page. Seek genuine mentions. Watch the Search Console reports.
Ongoing: Keep the sitemap and IndexNow current. Give robots.txt changes time to propagate. Earn citations. Make a deliberate choice about training crawlers. Treat llms.txt as optional. Re-check the CDN. Use Search Console’s Search generative AI control if you want to stay out of Google’s Search generative features.
Do those steps and you have done the part you control. The engines and the model trainers still decide what they keep, and when.
Discover more from Sulat AI & Tech News
Subscribe to get the latest posts sent to your email.