Artificial Analysis says Google has released its first decision model, Gemini Decision 1, and has scored it at 66 on the firm’s Decision Index v2.1. That sits in line with Base Labs’ Elephant 9B and TypeSafe’s Jev 1.14, and seven points behind the current leaders, Nace AI’s Drex Max v1.1 and Fastino’s GLiDE v1.2, which both score 73. The chart Artificial Analysis posted also shows Mammoth 27B and d1-ultra ahead of Gemini Decision 1, both at 71.
Google has now published the product itself. In a post by Min Choi, a product manager at Google DeepMind, and Felix Yu, a principal scientist there, the company introduces the Gemini Decisions API, powered by Gemini Decision 1 (gemini-decision-1), through the Gemini API in Google AI Studio. The official Google AI Studio account posted the same news. Google’s model documentation is live too.
introducing the Gemini Decisions API powered by Gemini Decision 1, our new multimodal decision model
November 11, 2026
Google has released its first decision model, Gemini Decision 1, scoring 66 on the Artificial Analysis Decision Index and leading in knowledge and reasoning benchmarks
November 11, 2026
What a decision model does
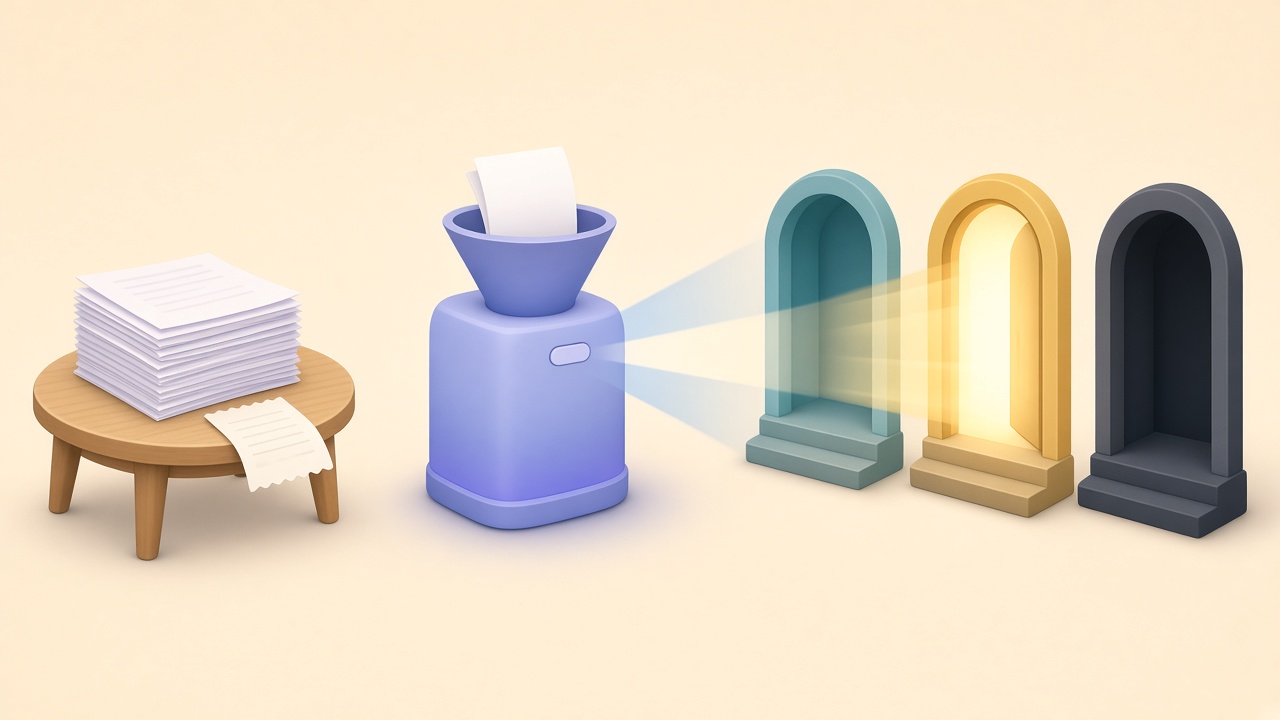
| Stage | What it shows |
|---|---|
| The document to judge | The text, or state, the model has to decide about |
| One call | The model answers the task’s questions in a single pass |
| A probability for each option | For a choice, it returns a probability for every option |
Per Artificial Analysis’s methodology, a decision model is given a state — the text to decide about — and one or more questions. Each question is a choice among named options, a score on a scale, or a yes/no question. The model answers all of a task’s questions in a single call, and for a choice it returns the option it picks plus a probability for every option.
Google’s blog says the Decisions API can evaluate up to 1,000 yes/no, choice and rubric-scoring questions in a single pass across text, images, audio, video and PDFs, and that it returns probabilities and confidence scores in 150 to 250 milliseconds end-to-end. Median model compute is given as 50 to 100 milliseconds, remaining nearly flat from 1 to 100 questions per request on contexts up to 16K tokens. The model page lists an input limit of 262,144 tokens, which is the 256K figure in the blog, and an output limit of zero tokens. Yes/no answers return a probability from 0.01 to 0.99; choice and rubric questions accept 2 to 255 options or levels. Google calls the yes/no type noul.
A first-party call looks like this, from the model documentation:
from google import genai

client = genai.Client(http_options={"api_version": "v1beta"})

result = client.decisions.create(
    model="gemini-decision-1",
    input="The blue mug I ordered on Monday arrived cracked on Wednesday.",
    questions={
        "is_damaged": {
            "type": "noul",
            "instructions": "Did the item arrive damaged?",
        },
        "queue": {
            "type": "choice",
            "instructions": "Which support queue should handle this message?",
            "criteria": {
                "billing": "Payment, invoice, or refund questions.",
                "replacements": "Damaged, missing, or wrong items.",
                "general": "Product questions and account updates.",
            },
        },
    },
)
The blog also says teams inside Google already use the API as a low-latency control plane: as a router in Gemini Notebook, where it says everyday queries can be served with up to 40% lower latency; in a rapid canvas experiment in Stitch; for emoji selection in CC from Google Labs; and as a safety layer for MCP tools in Search. Support for Gemini in Google Cloud is described as coming soon.
Using it from the AI SDK
Vercel’s AI SDK has wired the same model into experimental_decide. The official AI SDK account posted a short example, and a Vercel changelog by Aayush Kapoor, Jerilyn Zheng and Zachary Chen says Gemini Decision 1 is now available on AI Gateway as google/gemini-decision-1.
Use the Gemini Decisions API with the AI SDK
November 11, 2026
The AI SDK docs say this API and the decision model specification are experimental and may change in patch releases. You can pass a provider model instance, as in the official example:
import { google } from '@ai-sdk/google';
import { experimental_decide as decide } from 'ai';

const { answers } = await decide({
  model: google.decisionModel('gemini-decision-1'),
  state: 'I was charged twice. Please refund me.',
  questions: {
    refund: {
      type: 'boolean',
      instructions: 'Is a refund requested?',
    },
  },
});

console.log(answers.refund.probability);
String IDs resolve through AI Gateway by default. The changelog’s example uses model: 'google/gemini-decision-1'. Vercel also documents a TypeSafe-compatible client and a /v1/decisions HTTP API on the Gateway. It says PDF, audio and video inputs are supported through AI SDK 7, while the TypeSafe-compatible and Decisions APIs on the Gateway support text and image inputs.
The Decisions docs now list Google’s Decisions API as a native decision provider, alongside TypeSafe’s Jev, OpenAI’s Decisions API and Perplexity. Choice and Score answers include native probability distributions. The Google provider docs say the factory calls the Decisions API on v1beta, is not available on Vertex AI, and requires Decisions EAP access. Confidence values are exposed at result.providerMetadata.google.confidence. Generation options such as maxOutputTokens and reasoning controls are unsupported and produce warnings.
Two different scorecards
Google’s announcement includes a comparison table covering JevBench, Amazon ESCI, New Yorker Caption, Mind2Web, PubMedQA, Global-MMLU-Lite, When2Call, MMAU and Video-MME, plus a calibration and cost row. In that table, Gemini Decision 1 led most of the accuracy rows against TypeSafe’s Jev 1.14, OpenAI’s GPT-6 Luna Decisions API, and Gemini 3.5 Flash-Lite used through the Interactions API. It also had the lowest Top-1 expected calibration error, 0.0250, on the seven shared evaluations. Jev 1.14 led on Mind2Web Multimodal, at 86.8% against 86.2%, and on When2Call, at 82.0% against 79.9%, and was cheaper on the table’s cost row, at US$0.68 against US$0.88 for Gemini Decision 1 and US$0.93 for GPT-6 Luna. A footnote says refusals, safety blocks, and requests a model could not accept are scored as incorrect, and that scores are top-1 accuracy unless otherwise noted. The blog says Gemini Decision 1 was nearly five times cheaper across that shared suite than Gemini 3.5 Flash-Lite with the Interactions API.
Artificial Analysis’s Decision Index is a different suite. On that index Gemini Decision 1 sits mid-pack. The two sets of figures measure different work.
Where it led, and where it trailed, on the index
Artificial Analysis says Gemini Decision 1 leads the knowledge and reasoning evaluations in the index, at 66 on AA-Omniscience-Decision and 49 on HLE-MultiChoice. It trails on other tests, including the firm’s new document classification and extraction benchmark, AA-Paperclip. On that test, it answers all 15 questions correctly on 33% of documents, against 63% for Drex Max v1.1.
AA-Paperclip is 30% of the index. It’s built from 1,500 private resumes, receipts, invoices and research papers. Each document is asked as two tasks, five decisions and ten facts, and is scored as one decision: all 15 answers have to be right, and the model’s confidence is the product of its 15 chosen-answer probabilities.
Cost
Google prices Gemini Decision 1 at US$0.10 per 1 million input tokens and US$0 for output tokens, and says there’s a no-cost API tier in Google AI Studio for prototyping. The shared input is billed once per request, no matter how many questions you evaluate; each question adds only its own instruction and criteria tokens.
Artificial Analysis, using its own task mix, puts the cost at US$345 per 1 million tasks across the Decision Index. Drex Max v1.1 is priced at US$0.03 per 1 million input tokens and US$103 per 1 million tasks. Jev 1.14 is US$156 per 1 million tasks. GPT-6 Luna (Decisions) is close to Gemini Decision 1 on that measure, at US$339. A follow-up chart places Celeris-1.1 Decision at US$14 and Decider v1.2 at US$68 on the cost-versus-score Pareto frontier, with Drex Max v1.1 at the high-score end of that line. Gemini Decision 1 sits off that frontier.
Gemini Decision 1 costs $345 per 1M Tasks across the Artificial Analysis Decision Index. In comparison, Drex Max v1.1 has a Cost per 1M Tasks at $103, with Decider v1.2 ($68) and Celeris-1.1 Decision ($14) making up the rest of the decision models on the Decision Index vs. Cost
November 11, 2026
Calibration
Artificial Analysis measures calibration with the Brier score, the average squared gap between the probability a model assigns to its chosen answer and whether that answer was correct. Lower is better. Gemini Decision 1 has a Brier score of 0.18 across the index, between Drex Max v1.1 at 0.16 and Jev 1.14 at 0.19. On HLE-MultiChoice its Brier score is 0.20, which Artificial Analysis says is among the lowest in the index. On When2Call it’s 0.14, against 0.04 for Drex Max v1.1.
The Decision Score that makes up most of the index combines accuracy with that calibration. A right, certain answer scores 100 and a wrong, certain one scores 0, with 50 the line between right and wrong. Artificial Analysis writes the score as 50 × (1 + accuracy − Brier).
How the index is weighted
Version 2.1 combines six evaluations: AA-Paperclip at 30%, EvalSafe-O*NET-AA at 15%, When2Call at 10%, AA-Omniscience-Decision v1.1 at 15%, HLE-MultiChoice v1.1 at 15%, and AA-Symmetry v1.1 at 15%. The last of those uses a Symmetry Score, which checks that a decision holds when its options are moved or reworded, or the question is negated, rather than whether the answer is right.
The live index and the methodology are on Artificial Analysis’s site. Google’s guides and the AI SDK Decisions docs are the starting points for calling the model.
Discover more from Sulat AI & Tech News
Subscribe to get the latest posts sent to your email.