OpenAI today releases text-embedding-ada-002 through its embeddings API, combining five previously separate models: text similarity, text-search queries and documents, and code-search text and code.
Embeddings represent text or code as number sequences that can be compared for meaning. For search, an application compares a query’s vector with document vectors to rank relevant material, reducing dependence on exact wording. OpenAI’s January endpoint launch provided separate model families for similarity, text search and code search.
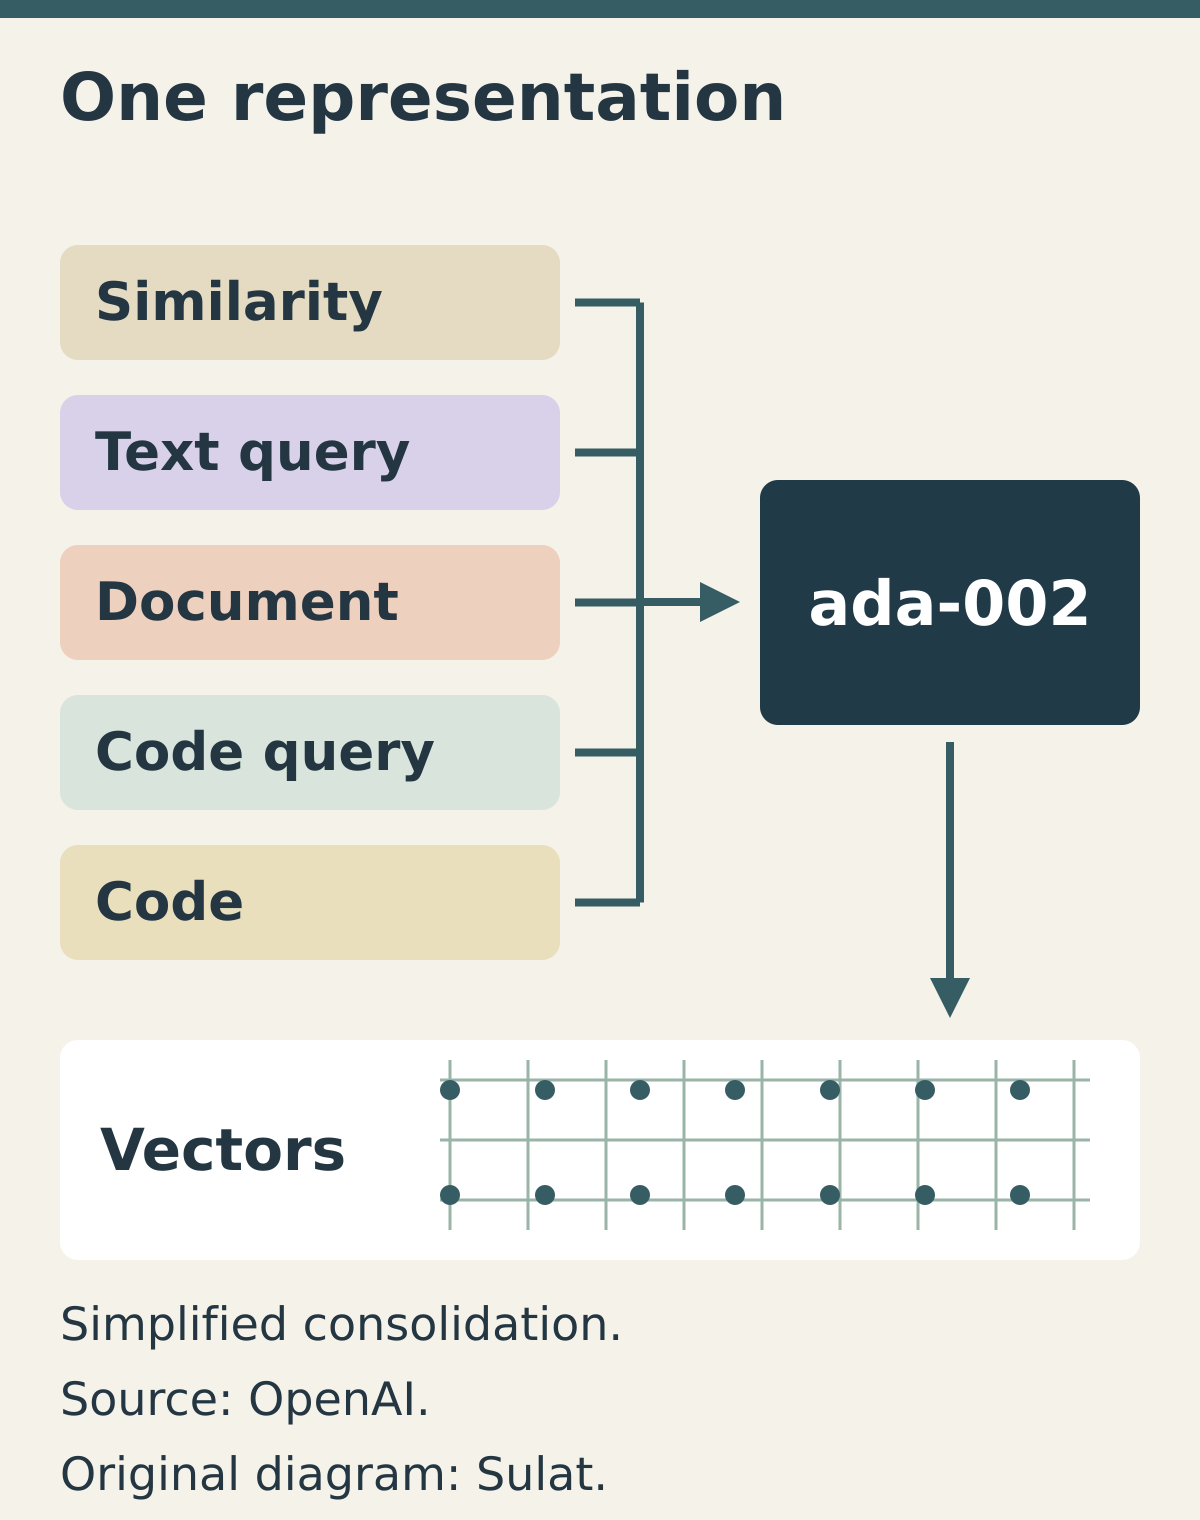
Inputs can span 8,192 tokens, up from 2,048. Outputs contain 1,536 dimensions, one-eighth the size of davinci-001 embeddings.
OpenAI reports stronger text-search, code-search and sentence-similarity results. Pricing is 90% lower than older models of the same size and 99.8% lower than the old Davinci models.
On SentEval’s linear-probe classification benchmark, the new model does not beat text-similarity-davinci-001. OpenAI recommends comparing both when training a lightweight linear classifier on embedding vectors.
Discover more from Sulat AI & Tech News
Subscribe to get the latest posts sent to your email.