Anthropic today publishes Constitutional AI, research using written principles and model feedback to train assistants without human labels identifying harmful outputs.
Illustration: Sulat. Wordmark: Anthropic.
The work follows Anthropic’s April research on reinforcement learning from human feedback. In that approach, people compare pairs of responses, producing separate datasets for helpfulness and harmfulness. A preference model learns from those judgments and supplies rewards for further training. The underlying challenge is balancing useful answers with avoiding harmful assistance.
The new method starts with an assistant critiquing and revising responses against written principles. Those revisions provide supervised training data. AI comparisons then train a preference model for reinforcement learning.
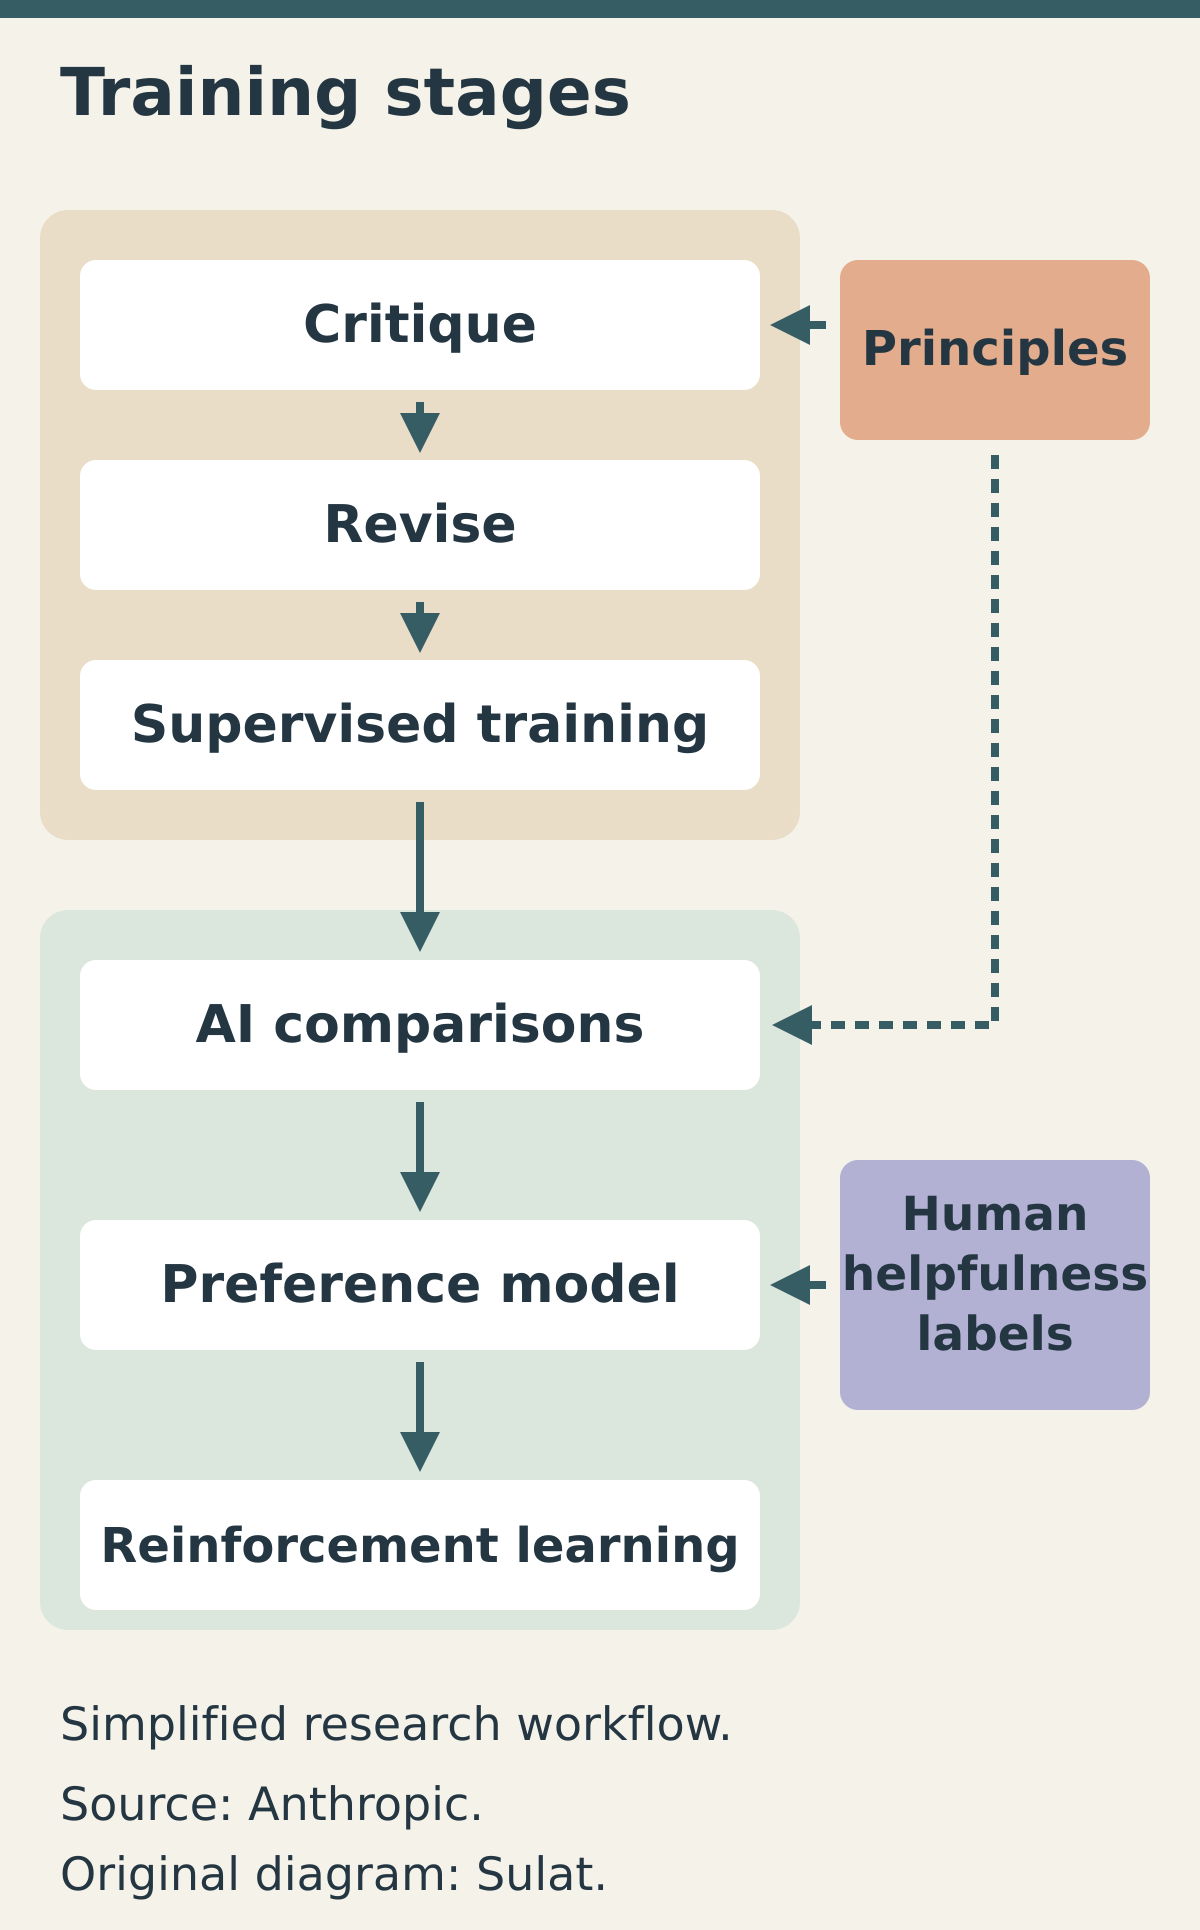
Human-written principles, examples and helpfulness labels remain. Anthropic reports improved human-rated harmlessness with less evasiveness. Evaluators favour engagement over evasion when responses are equally harmless. The goal is to explain objections to harmful requests while retaining useful discussion. Robustness against adversarial prompts remains an open research problem.
Discover more from Sulat AI & Tech News
Subscribe to get the latest posts sent to your email.