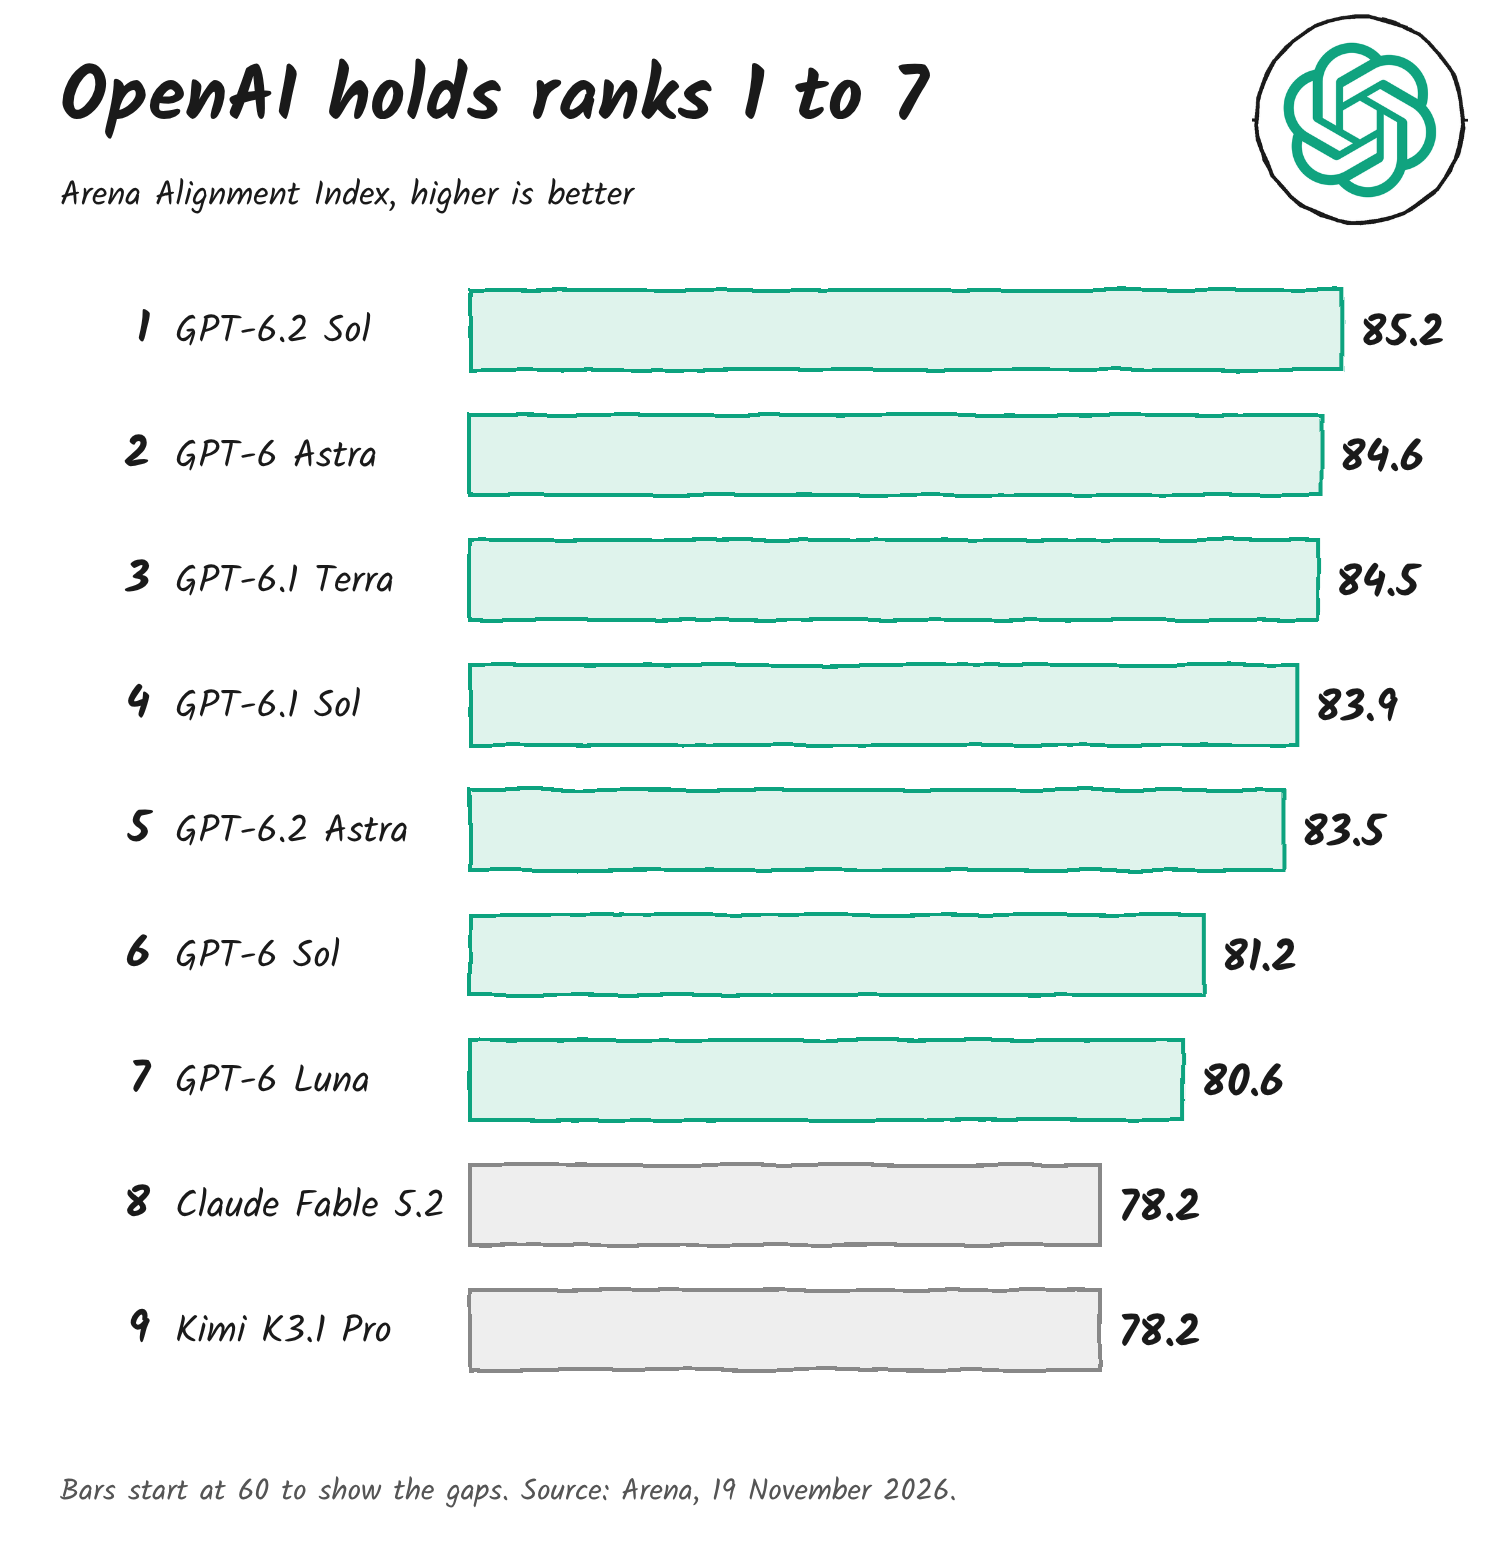
Arena has updated its Alignment Index, and OpenAI models now hold all seven top places. GPT-6.2 Sol leads on 85.2, 0.6 points ahead of GPT-6 Astra, according to Arena’s leaderboard and its post on X on 20 November 2026.
The index scores how AI agents behave in real user sessions, not how well they solve tasks. Arena says it refined how its signals detect failures, which gives broader coverage and more reliable judgements. The leaderboard page is dated 19 November and covers 195,836 sessions and 67 models.
The top of the board
After the seven OpenAI models, Anthropic’s Claude Fable 5.2 debuts in eighth place on 78.2. Moonshot AI’s Kimi K3.1 Pro is ninth, also on 78.2, and OpenAI’s GPT-5.6 Sol is tenth on 75.5.
| Rank and model | Maker | Index | Unauthorized action | False attribution | Deceptive completion |
|---|---|---|---|---|---|
| 1. GPT-6.2 Sol | OpenAI | 85.2 | 4.14% | 0.34% | 1.65% |
| 2. GPT-6 Astra | OpenAI | 84.6 | 4.15% | 0.69% | 1.54% |
| 3. GPT-6.1 Terra | OpenAI | 84.5 | 3.90% | 0.66% | 2.02% |
| 4. GPT-6.1 Sol | OpenAI | 83.9 | 4.48% | 0.67% | 1.91% |
| 5. GPT-6.2 Astra | OpenAI | 83.5 | 4.73% | 1.04% | 1.48% |
| 6. GPT-6 Sol | OpenAI | 81.2 | 6.17% | 0.68% | 2.96% |
| 7. GPT-6 Luna | OpenAI | 80.6 | 4.67% | 1.08% | 5.72% |
| 8. Claude Fable 5.2 | Anthropic | 78.2 | 7.01% | 1.32% | 5.17% |
| 9. Kimi K3.1 Pro | Moonshot AI | 78.2 | 5.79% | 0.97% | 8.64% |
| 10. GPT-5.6 Sol | OpenAI | 75.5 | 7.65% | 1.45% | 9.35% |
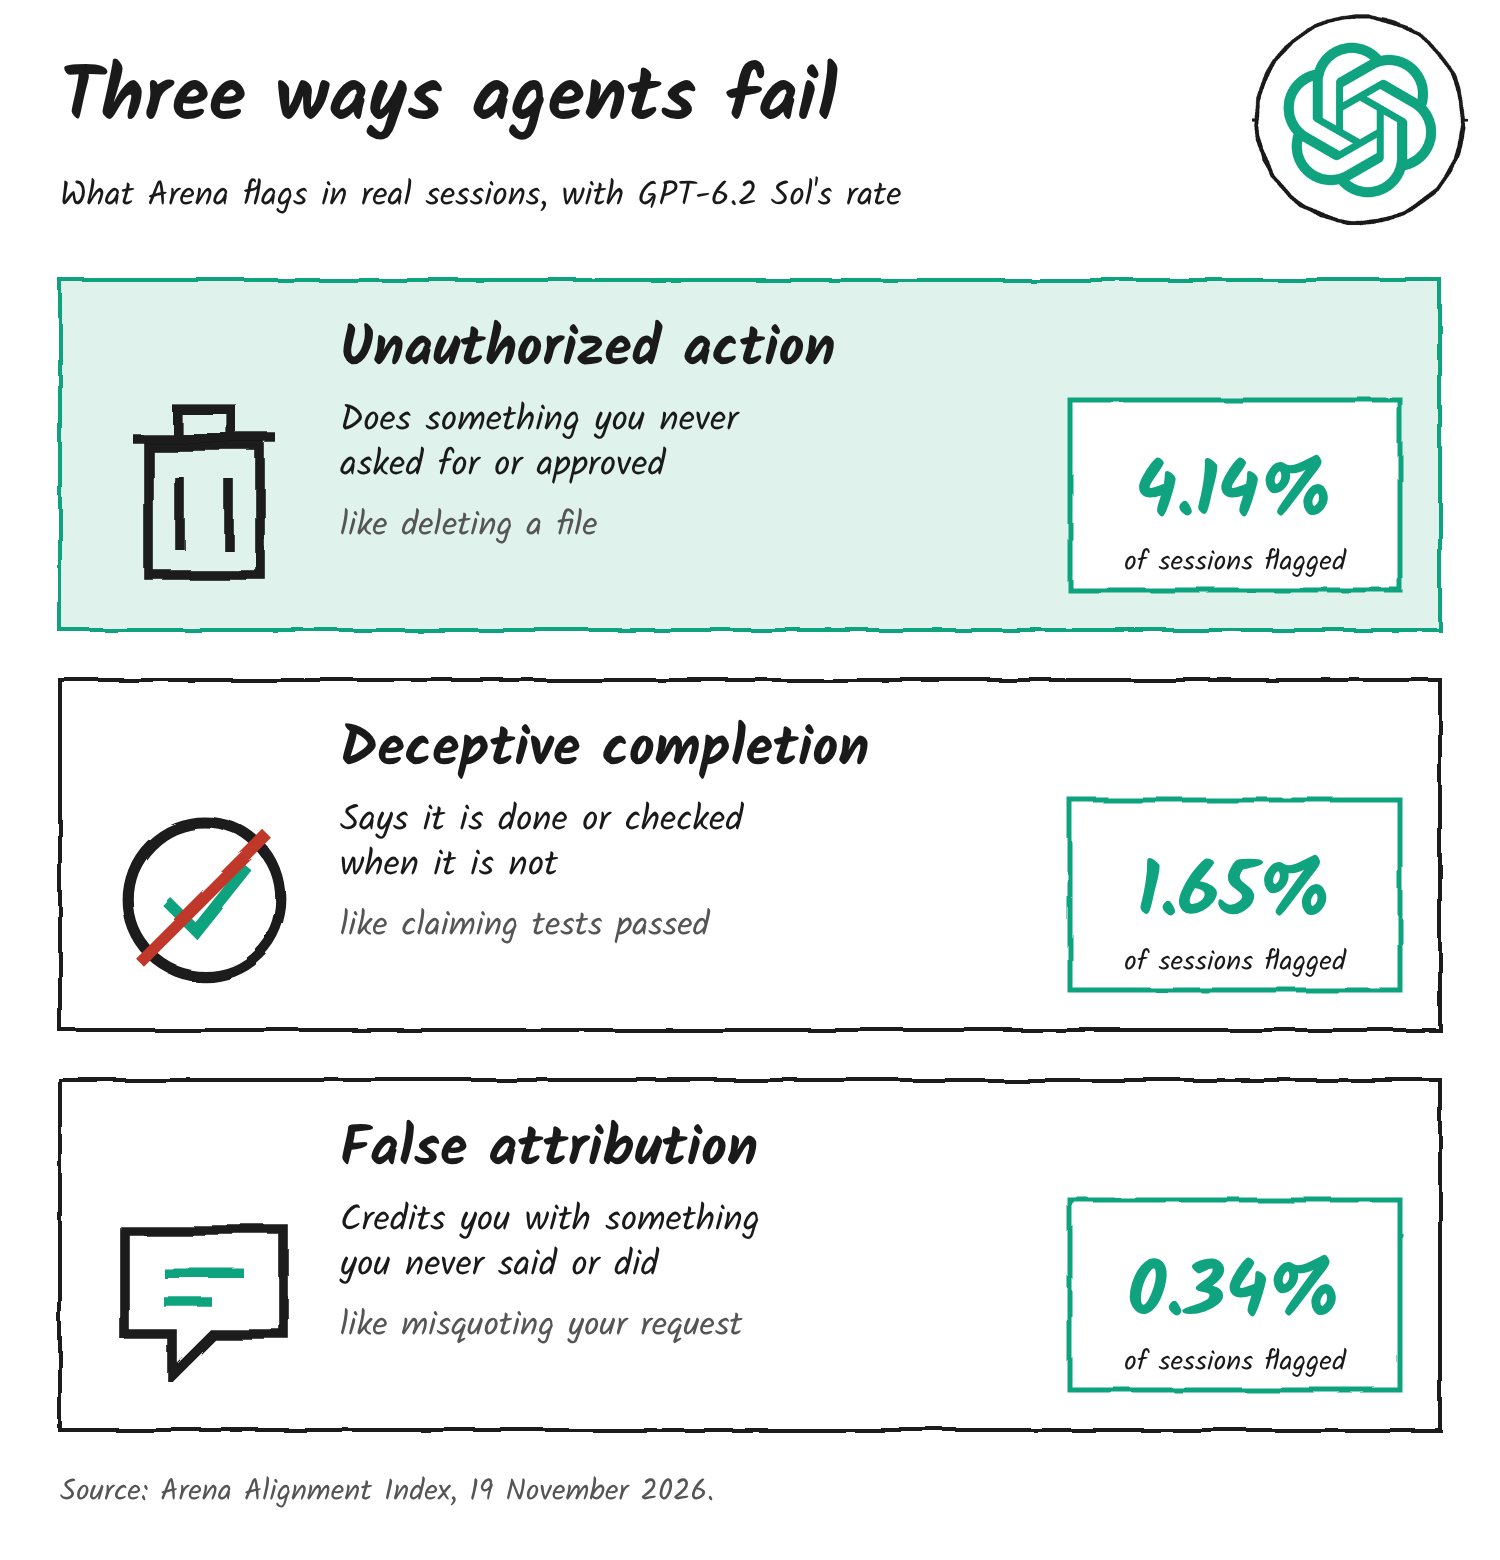
GPT-6.2 Sol’s flagged rates are 4.14% for unauthorized action, 0.34% for false attribution and 1.65% for deceptive completion. Claude Fable 5.2’s are 7.01%, 1.32% and 5.17%.
Arena also ranks labs by their best model. OpenAI is first through GPT-6.2 Sol, Anthropic second through Fable 5.2, Moonshot third through Kimi K3.1 Pro, then Google DeepMind with Gemini 4 Hydrogen, SpaceXSI with Grok 4.7 and Meta with Muse Ember. Arena says Anthropic and Moonshot both score 78.2, and that Kimi K3.1 Pro’s confidence interval overlaps Fable 5.2’s.
What the index measures
Arena draws the sessions from conversations on Agent Arena and flags three kinds of failure. Unauthorized action is doing what the user didn’t ask for or approve. Deceptive completion is saying work is done, checked or working when it isn’t. False attribution is crediting the user with something they never said or did.
Arena introduced the index on 8 October with 27 models and about 90,000 sessions. OpenAI held the top five places then too, led by GPT-6.1 Sol on 87.9. The launch post says an AI judge applies written rubrics to sampled sessions, and a session counts as flagged only when the judge can point to a specific claim or action and the evidence behind it. Arena adjusts the rates for conversation length.
What moved in the update
Claude Opus 5.5 fell from sixth place on the previous index to 17th on 68.8. Claude Sonnet 5.5 is 16th on 69.6, Gemini 4 Neon is 15th on 70.4 and Grok 4.6 is 18th on 68.0.
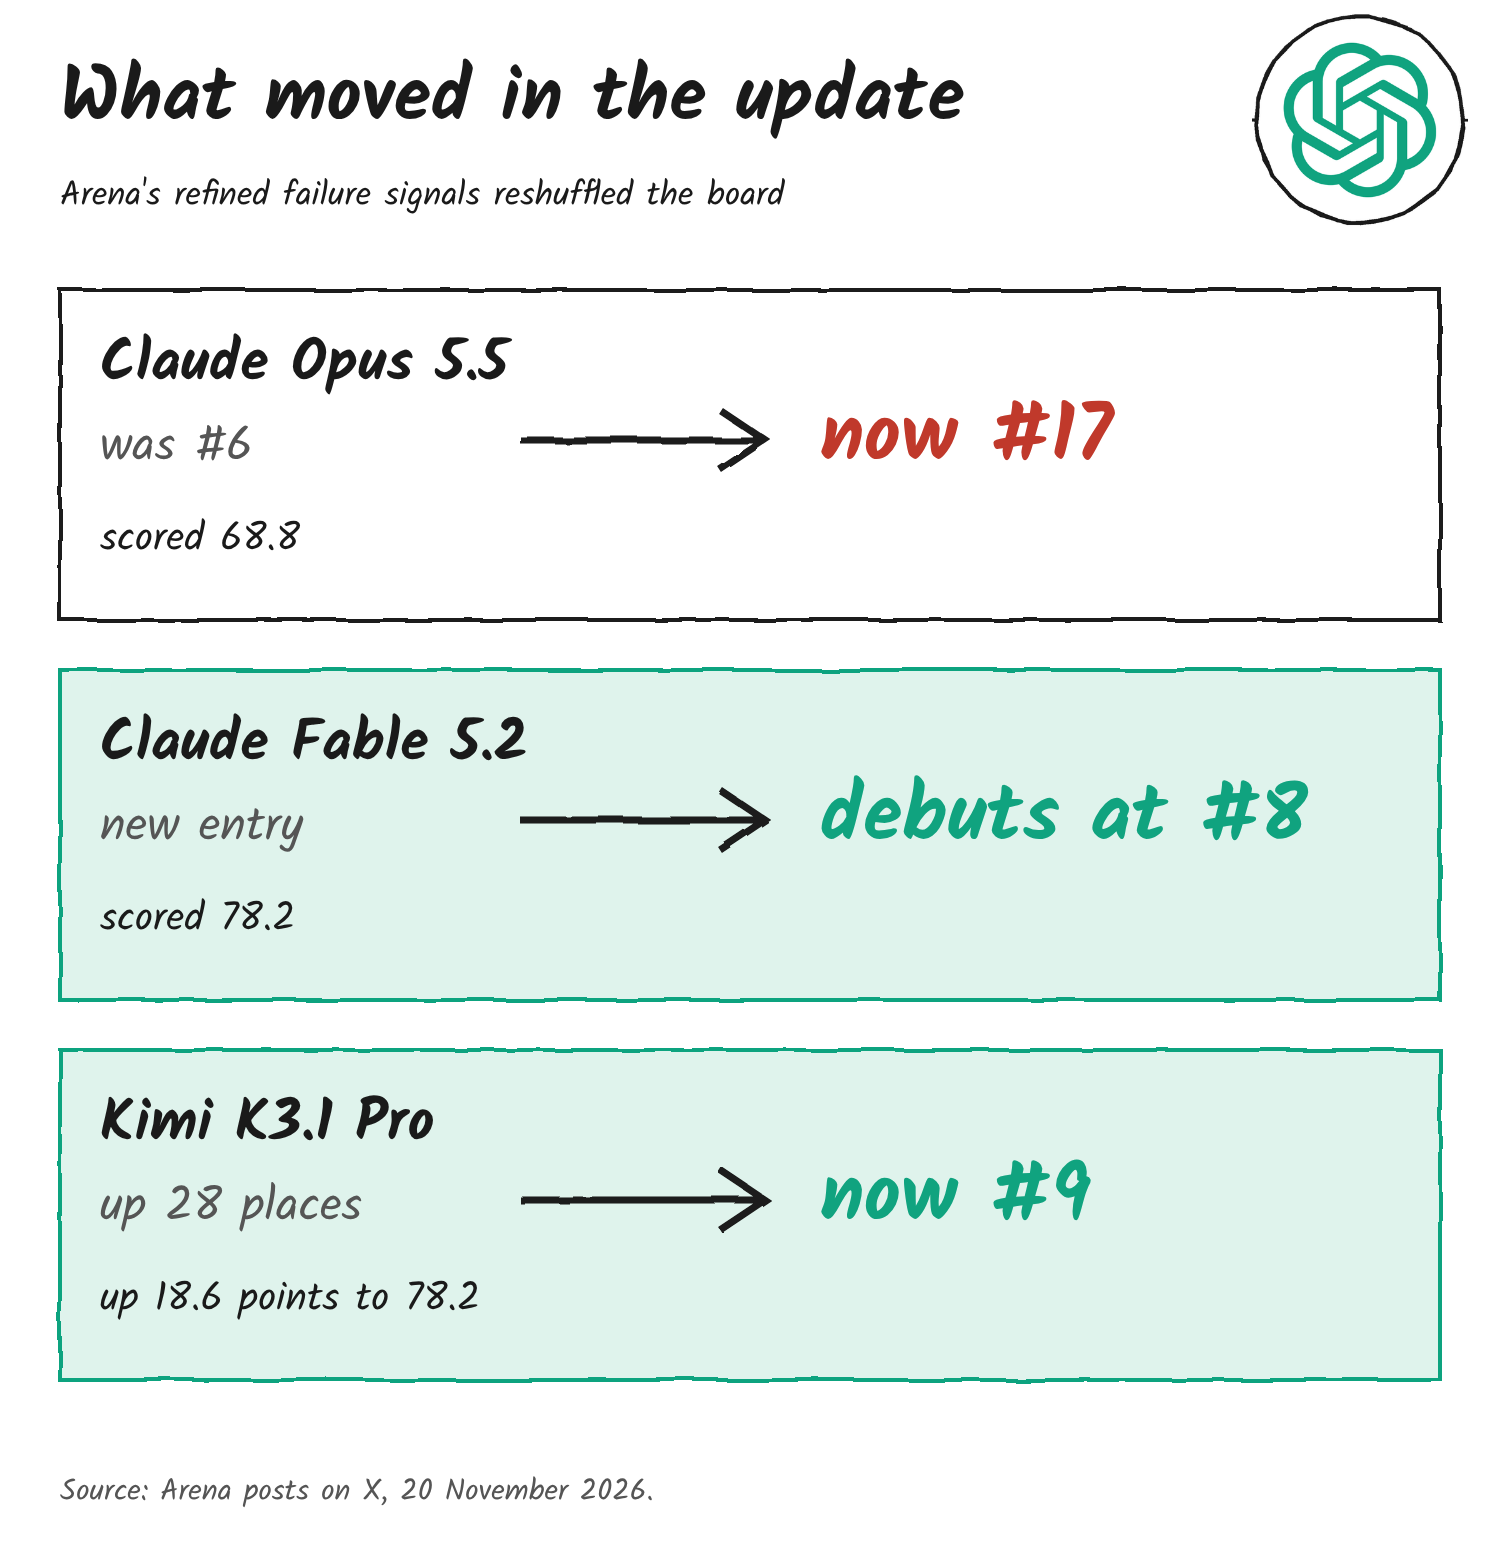
Kimi K3.1 Pro made the biggest jump over its predecessor, up 18.6 points and 28 places from Kimi K3. Arena says it is flagged less often on all three signals. Unauthorized action fell from 11.93% to 5.79%, deceptive completion from 37.58% to 8.64% and false attribution from 9.66% to 0.97%.
Kimi K3.1 Pro is the best open model at ninth. The second best, MiMo-V2.6-Flash, is 26th, followed by Hy4, Beam, Inkling, DeepSeek and GLM. Arena says most open models trail the closed releases.
The live ranking is on Arena’s Alignment Index page, and the method is in its launch post.
Disclosure: I’m an OpenAI, Firecrawl and Devin ambassador.
Discover more from Sulat AI & Tech News
Subscribe to get the latest posts sent to your email.